




 README

go-json


Fast JSON encoder/decoder compatible with encoding/json for Go
Features
- Drop-in replacement of
encoding/json. Values are decoded, and their errors are reported, asencoding/jsonof Go 1.27 (built onencoding/json/v2) does, on every Go version. Only the syntax errors of decoding and the reading of a stream token by token (Token,More,InputOffset, andDecodebetween calls ofToken) follow theencoding/jsonthe program is built with. Values are encoded as theencoding/jsonthe program is built with encodes them, except for some behaviors of Go 1.27 that apply on every version, such as the limit of 10000 nested levels, map keys of pointer types, and the syntax errors ofMarshalJSONoutput,CompactandIndent. TheMarshalJSONToandUnmarshalJSONFrommethods are called beforeMarshalJSONandUnmarshalJSON, asencoding/jsonof Go 1.27 calls them: the ones which take theEncoderand theDecoderofgithub.com/goccy/go-json/jsontextfirst, on every Go version, and the ones which take those ofencoding/json/jsontextwhere the program is built with Go 1.27. Asencoding/jsondoes, they are given an encoder and a decoder with the options ofencoding/json(DefaultOptionsV1), and the decoder with the ones ofDisallowUnknownFieldsandUseNumberof aDecoder, so thatMarshalEncodeandUnmarshalDecodewithin the methods encode and decode as this package does;UseNumberis given only to the methods ofgithub.com/goccy/go-json/jsontext, asencoding/jsonexports no option of it. - Drop-in replacement of
encoding/json/v2andencoding/json/jsontextbygithub.com/goccy/go-json/v2andgithub.com/goccy/go-json/jsontext, with the API and behavior of those packages of Go 1.27 on Go 1.23 and later, with no need ofGOEXPERIMENT=jsonv2. Their types are their own, not aliases of the ones of the standard library: replace both imports together, and declareMarshalJSONToandUnmarshalJSONFrommethods with theEncoderandDecoderofgithub.com/goccy/go-json/jsontext, since methods taking the ones ofencoding/json/jsontextare not called. - Fast ( See Benchmark section )
MarshalOfandUnmarshalOf, which take the value by its type and save the allocationsMarshalandUnmarshalneed for aninterface{}argument- Flexible customization with options
- Coloring the encoded string
- Can propagate context.Context to
MarshalJSONorUnmarshalJSON - Can dynamically filter the fields of the structure type-safely
Installation
go get github.com/goccy/go-json
How to use
Replace import statement from encoding/json to github.com/goccy/go-json
-import "encoding/json"
+import "github.com/goccy/go-json"
Code which uses encoding/json/v2 or encoding/json/jsontext replaces them likewise
-import "encoding/json/v2"
+import "github.com/goccy/go-json/v2"
-import "encoding/json/jsontext"
+import "github.com/goccy/go-json/jsontext"
JSON library comparison
| name | encoder | decoder | compatible with encoding/json |
|---|---|---|---|
| encoding/json | yes | yes | N/A |
| json-iterator/go | yes | yes | partial |
| easyjson | yes | yes | no |
| gojay | yes | yes | no |
| segmentio/encoding/json | yes | yes | partial |
| jettison | yes | no | no |
| simdjson-go | no | yes | no |
| bytedance/sonic | yes | yes | partial |
| goccy/go-json | yes | yes | yes |
json-iterator/goisn't compatible withencoding/jsonin many ways (e.g. https://github.com/json-iterator/go/issues/229 ), but it hasn't been supported for a long time.segmentio/encoding/jsonis well supported for encoders, but some are not supported for decoder APIs such asToken( streaming decode )bytedance/sonicis compatible withencoding/jsonin itsConfigStdconfiguration; by default it doesn't escape HTML, sort the keys of maps or validate strings. It decodes and encodes by native code: SIMD code and, on amd64, code generated at run time. The benchmarks of this repository compare go-json with sonic in both configurations ( see below ).
Other libraries
I tried the benchmark but it didn't work. Also, it seems to panic when it receives an unexpected value because there is no error handling...
Benchmarking gave very slow results. It seems that it is assumed that the user will use the buffer pool properly. Also, development seems to have already stopped
Benchmarks
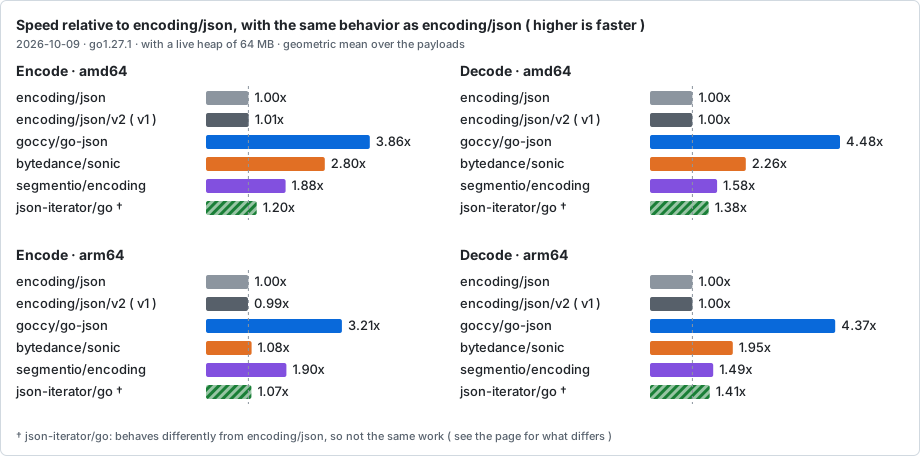
The JSON libraries of Go are measured doing the same work on GitHub Actions, on amd64 and arm64, and the results are published at https://goccy.github.io/go-json/, measured again whenever go-json, the version of a library or the report changes. The page has every payload, the encode and decode of each library, the allocations, and the results without a live heap.
A comparison is fair only between libraries doing the same work, so the results are shown by category of behavior: the behavior of encoding/json, the behavior of encoding/json/v2, the behavior of encoding/json without HTML escaping, key sorting and string copying, and every library at its fastest. In each category, every library is configured by its options to behave as the category requires, as far as its options allow, and as fast as they allow. Every run checks the behavior of each library on small probes before it measures it, and a library which behaves differently is still shown, marked, with what differs. The result files are attested by GitHub Artifact Attestations: gh attestation verify tells that they were produced by the workflow of this repository.
To run the report locally:
$ make bench-report
To compare go-json with bytedance/sonic side by side, benchmark by benchmark:
$ make bench-compare-encode
$ make bench-compare-decode
BENCH_LIVE_HEAP_MB=64 make bench-compare-decode runs the decode benchmarks with 64 MB of live heap, as a real program has: the GC then runs less often, as it does in such a program.
Fuzzing
go-json-fuzz is the repository for fuzzing tests. If you run the test in this repository and find a bug, please commit to corpus to go-json-fuzz and report the issue to go-json.
How it works
go-json is very fast in both encoding and decoding compared to other libraries.
It's easier to implement by using automatic code generation for performance or by using a dedicated interface, but go-json dares to stick to compatibility with encoding/json and is the simple interface. Despite this, we are developing with the aim of being the fastest library.
Here, we explain the various speed-up techniques implemented by go-json.
Basic technique
The techniques listed here are the ones used by most of the libraries listed above.
Buffer reuse
Since the only value required for the result of json.Marshal(interface{}) ([]byte, error) is []byte, the only value that must be allocated during encoding is the return value []byte .
Also, as the number of allocations increases, the performance will be affected, so the number of allocations should be kept as low as possible when creating []byte.
Therefore, there is a technique to reduce the number of times a new buffer must be allocated by reusing the buffer used for the previous encoding by using sync.Pool.
Finally, you allocate a buffer that is as long as the resulting buffer and copy the contents into it, you only need to allocate the buffer once in theory.
type buffer struct {
    data []byte
}

var bufPool = sync.Pool{
    New: func() any {
        return &buffer{data: make([]byte, 0, 1024)}
    },
}

buf := bufPool.Get().(*buffer)
data := encode(buf.data) // reuse buf.data

newBuf := make([]byte, len(data))
copy(newBuf, buf)

buf.data = data
bufPool.Put(buf)
Elimination of reflection
As you know, the reflection operation is very slow.
Therefore, using the fact that the address position where the type information is stored is fixed for each binary ( we call this typeptr ),
we can use the address in the type information to call a pre-built optimized process.
For example, you can get the address to the type information from interface{} as follows and you can use that information to call a process that does not have reflection.
To process without reflection, pass a pointer (unsafe.Pointer) to the value is stored.
type emptyInterface struct {
    typ unsafe.Pointer
    ptr unsafe.Pointer
}

var typeToEncoder = map[uintptr]func(unsafe.Pointer)([]byte, error){}

func Marshal(v any) ([]byte, error) {
    iface := (*emptyInterface)(unsafe.Pointer(&v)
    typeptr := uintptr(iface.typ)
    if enc, exists := typeToEncoder[typeptr]; exists {
        return enc(iface.ptr)
    }
    ...
}
※ In reality, typeToEncoder can be referenced by multiple goroutines, so exclusive control is required.
Unique speed-up technique
Encoder
Encode a value without copying it to the heap by MarshalOf
json.Marshal receives an interface{} value. A value which is not a pointer is copied to the heap when it is converted to an interface{} value, so json.Marshal(v) allocates the copy of v for every call, in addition to the result.
json.MarshalOf[T] receives the value by its type. It copies the value to a value in the heap which is reused, so the result is the only allocation.
b, err := json.MarshalOf(v)
Which one to use depends on what is passed:
| What is passed | Recommended | Why |
|---|---|---|
A value which is not a pointer ( a struct, an int, a string, ... ) |
json.MarshalOf(v) |
It saves the allocation of the copy: about 15% faster for a small struct. v can also stay on the stack of the caller, which json.Marshal(&v) doesn't allow. |
| A pointer or a map | either | Such a value is stored in an interface{} value without an allocation, so they are the same. |
A large value which is already referred to by a pointer p |
json.Marshal(p) |
json.MarshalOf(*p) copies the whole value, which costs more as the value gets larger. |
MarshalNoEscape, which left the value on the stack, is deprecated: the encoder refers to the value by its address, and the address gets invalid when the stack of the goroutine is moved. It is now the same as Marshal.
Let the encoder order the fields of a struct by OptimizeFieldOrder
encoding/json writes the fields of a struct in the order of the struct, and so does go-json by default. A JSON object doesn't define the order of its keys, so when the order doesn't matter to the reader of the JSON, the option json.OptimizeFieldOrder() lets the encoder order the fields as it encodes them fastest:
b, err := json.MarshalWithOption(v, json.OptimizeFieldOrder())
- The fields of the same kind (
int,uint,float64,string,bool) are put together, in the order of the first field of each kind, and are encoded without a dispatch of the VM between them ( see below ). - A field of the struct's own type ( the next node of a list ), if there is one, is put last, so that a list of values is encoded in one frame of the VM instead of one frame for each value.
The keys are the same, only their order differs. The opcodes of a type are compiled for the option apart from the ones in the order of the struct, so the two can be used together.
Encoding using opcode sequence
I explained that you can use typeptr to call a pre-built process from type information.
In other libraries, this dedicated process is processed by making it an function calling like anonymous function, but function calls are inherently slow processes and should be avoided as much as possible.
Therefore, go-json adopted the Instruction-based execution processing system, which is also used to implement virtual machines for programming language.
If it is the first type to encode, create the opcode ( instruction ) sequence required for encoding.
From the second time onward, use typeptr to get the cached pre-built opcode sequence and encode it based on it. An example of the opcode sequence is shown below.
json.Marshal(struct{
    X int `json:"x"`
    Y string `json:"y"`
}{X: 1, Y: "hello"})
When encoding a structure like the one above, create a sequence of opcodes like this:
- opStructFieldHead ( `{` )
- opStructFieldInt ( `"x": 1,` )
- opStructFieldString ( `"y": "hello"` )
- opStructEnd ( `}` )
- opEnd
※ When processing each operation, write the letters on the right.
In addition, each opcode is managed by the following structure ( Pseudo code ).
type opType int
const (
    opStructFieldHead opType = iota
    opStructFieldInt
    opStructFieldStirng
    opStructEnd
    opEnd
)
type opcode struct {
    op opType
    key []byte
    next *opcode
}
The process of encoding using the opcode sequence is roughly implemented as follows.
func encode(code *opcode, b []byte, p unsafe.Pointer) ([]byte, error) {
    for {
        switch code.op {
        case opStructFieldHead:
            b = append(b, '{')
            code = code.next
        case opStructFieldInt:
            b = append(b, code.key...)
            b = appendInt((*int)(unsafe.Pointer(uintptr(p)+code.offset)))
            code = code.next
        case opStructFieldString:
            b = append(b, code.key...)
            b = appendString((*string)(unsafe.Pointer(uintptr(p)+code.offset)))
            code = code.next
        case opStructEnd:
            b = append(b, '}')
            code = code.next
        case opEnd:
            goto END
        }
    }
END:
    return b, nil
}
In this way, the huge switch-case is used to encode by manipulating the linked list opcodes to avoid unnecessary function calls.
Opcode sequence optimization
One of the advantages of encoding using the opcode sequence is the ease of optimization. The opcode sequence mentioned above is actually converted into the following optimized operations and used.
- opStructFieldHeadInt ( `{"x": 1,` )
- opStructEndString ( `"y": "hello"}` )
- opEnd
It has been reduced from 5 opcodes to 3 opcodes !
Reducing the number of opcodees means reducing the number of branches with switch-case.
In other words, the closer the number of operations is to 1, the faster the processing can be performed.
In go-json, optimization to reduce the number of opcodes itself like the above and it speeds up by preparing opcodes with optimized paths.
Change recursive call from CALL to JMP
Recursive processing is required during encoding if the type is defined recursively as follows:
type T struct {
    X int
    U *U
}

type U struct {
    T *T
}

b, err := json.Marshal(&T{
    X: 1,
    U: &U{
        T: &T{
            X: 2,
        },
    },
})
fmt.Println(string(b)) // {"X":1,"U":{"T":{"X":2,"U":null}}}
In go-json, recursive processing is processed by the operation type of opStructFieldRecursive.
In this operation, after acquiring the opcode sequence used for recursive processing, the function is not called recursively as it is, but the necessary values are saved by itself and implemented by moving to the next operation.
The technique of implementing recursive processing with the JMP operation while avoiding the CALL operation is a famous technique for implementing a high-speed virtual machine.
For more details, please refer to the article ( but Japanese only ).
Dispatch by typeptr without a lock
When retrieving the data cached from the type information by typeptr, we usually use map.
Map requires exclusive control, so use sync.Map for a naive implementation.
However, this is slow: as a result of profiling, runtime.mapaccess2 accounted for a significant percentage of the execution time.
go-json looks up the cache in two steps, neither of which takes a lock:
- The runtime context, which is taken from a pool for every call, remembers the opcodes of the types it encoded last. Most of the programs encode the same types again and again, so this is a load and a comparison in most cases.
- Otherwise a hash table with open addressing is looked up by the address of the type. An entry is written once ( the value, and then the key, by the
atomicpackage ), and the table is replaced by a larger one when it gets half full, so a reader never waits for a writer. A value is stored only when a type is compiled for the first time.
An earlier version used a slice which had an element for every address a type of the program can be at, found by typelinks of the runtime package through go:linkname. It was replaced because it depended on the internals of the runtime, used memory in proportion to the size of the program, had to fall back to a map for a large program, and made the GC scan the whole slice in every cycle.
If you want to know more, please refer to the implementation here
Decoder
Dispatch by typeptr without a lock
Like the encoder, the decoder uses typeptr to call the decoder built for the type. The runtime context of a call remembers the decoders of the types it decoded last, and otherwise a hash table which is read without a lock is looked up, as the encoder does.
Decode a value without an allocation for the argument by UnmarshalOf
json.Unmarshal receives an interface{} value, which makes the value escape to the heap. json.UnmarshalOf[T] receives the pointer by its type: it decodes into a value in the heap which is reused and copies the result to *v, so v may point to a variable on the stack of the caller, and a value without a pointer, slice, map or string to fill is decoded without an allocation. With json.DecodeNoCopyString(), a string without an escape needs none either.
var v T
err := json.UnmarshalOf(data, &v)
The value is copied twice, so json.Unmarshal is faster for a large value which is in the heap anyway.
Faster termination character inspection using NUL character
In order to decode, you have to traverse the input buffer character by position. At that time, if you check whether the buffer has reached the end, it will be very slow.
buf : []byte type variable. holds the string passed to the decoder
cursor : int64 type variable. holds the current read position
buflen := len(buf)
for ; cursor < buflen; cursor++ { // compare cursor and buflen at all times, it is so slow.
    switch buf[cursor] {
    case ' ', '\n', '\r', '\t':
    }
}
Therefore, by adding the NUL (\000) character to the end of the read buffer as shown below, it is possible to check the termination character at the same time as other characters.
for {
    switch buf[cursor] {
    case ' ', '\n', '\r', '\t':
    case '\000':
        return nil
    }
    cursor++
}
Unmarshal copies the input once, into a buffer followed by the NUL character which the runtime context keeps from a call to the next, so the copy allocates nothing in most calls. The stream decoder ( Decoder ) puts the NUL character after the bytes it has read, and decodes a value that its buffer holds whole by the same decoders. An object decoded into a struct, a map or an interface{}, or an array decoded into a slice, an array or an interface{}, that its buffer does not hold whole, is decoded element by element, each element whole if the buffer holds it and element by element otherwise, so that the buffer holds one read and the longest token, whatever the size of the value. Any other object or array is read whole, such as one decoded into a type with an UnmarshalJSON method, or an array decoded into a struct.
Use Boundary Check Elimination
Due to the NUL character optimization, the Go compiler does a boundary check every time, even though buf[cursor] does not cause out-of-range access.
Therefore, go-json eliminates boundary check by fetching characters for hotspot by pointer operation. For example, the following code.
func char(ptr unsafe.Pointer, offset int64) byte {
	return *(*byte)(unsafe.Pointer(uintptr(ptr) + uintptr(offset)))
}

p := (*sliceHeader)(&unsafe.Pointer(buf)).data
for {
    switch char(p, cursor) {
    case ' ', '\n', '\r', '\t':
    case '\000':
        return nil
    }
    cursor++
}
Scanning strings eight bytes at a time, and by SIMD
A string is scanned a word ( eight bytes ) at a time: a few bit operations on the word tell whether one of its bytes is a quote, a backslash or a control character, and whether one is not ASCII, so a byte is looked at alone only where the string ends or has an escape. After its first 64 bytes, the rest of a long string is scanned by AVX2 on amd64.
A string with an escape is decoded in the same pass as it is scanned from its first escape on: the runs of plain bytes between the escapes are moved at once, and the escapes are validated and decoded as they are met.
Strings copied, or referring to the input
A decoded string is a copy of its own, as with encoding/json, so the input may be modified after the call, and a kept string keeps alive nothing but its bytes. The stream decoder copies the strings out of its buffer too, so that it reuses the buffer in place when it reads more. With the option json.DecodeNoCopyString(), a string without an escape refers to the input without a copy, and keeps it alive: the data given to Unmarshal, or the buffer of the stream decoder which the value was read into, which the decoder doesn't reuse then.
An earlier version copied the short strings into chunks of up to 16 KB shared by the strings of a runtime context, instead of an allocation for each: a small value kept out of a call kept a whole chunk alive, filled by the strings of other calls ( #775 ).
Finding the field of a key by its words
The fields of a struct are in a hash table keyed by their keys folded to lower case, and a key of the input is looked up by two words: its first eight bytes and its last eight bytes, which overlap for a key shorter than 16 bytes. A key of up to 16 bytes is compared by its length and these two words only, and a key of ASCII is folded eight bytes at a time, so a field is found by a few word operations whatever the number of fields and the length of the keys. A key matches the field with the same key, or else the first field with the same key by case folding, as with encoding/json.
An earlier version found the field by bitmaps of the characters of the keys, [maxKeyLength][256]int8 or int16. It was replaced because it worked only for structs of up to 16 fields and keys shorter than 64 bytes, and fell back to a map for the others.
Parsing numbers in one pass
The digits of a number are accumulated as they are read and validated by the grammar of JSON. A float with a mantissa of up to 19 digits is computed from the mantissa and a power of ten: directly when both are held exactly by a float64, and else by a table of the powers of ten as 128-bit significands. The result is the one of strconv.ParseFloat, which is called only for the rare numbers the table doesn't decide.
Skipping values while validating them
The value of a key which matches no field is not decoded, but it is still checked by the grammar of JSON, as encoding/json checks the whole input: an invalid value is a syntax error wherever it is. The skip is a state machine which calls no function in its loop, so that its state stays in the registers, and the rare cases it doesn't handle itself ( an escape, a number which is not an integer, a deep nesting ) are handled by its caller, which resumes it.
To find the end of an object or an array without decoding it, as the stream decoder does, the bytes are scanned 64 at a time: masks of the quotes, backslashes and brackets of a block are made by AVX2 on amd64, by NEON on arm64 and by words elsewhere, and a prefix XOR of the quotes tells which bytes are inside a string.
Decoding interface{} values without reflection
The values of an array or an object decoded into interface{} are pushed to a stack of the runtime context, and a []interface{} or a map[string]interface{} is made of their number at the end: a map filled entry by entry grows and moves its entries several times on the way. The empty arrays share one empty slice. A number or a string is stored into its interface{} value by itself, as with encoding/json: an earlier version stored them from slabs of a runtime context, which a kept value kept alive with the values of other calls ( #775 ).
Slices and maps of their own size
The elements of an array are decoded directly into the slice, which grows as append grows it, and the elements of a long array into a buffer which becomes the slice, allocated once, of its length. The zero values the entries of a map are decoded into are reused from a pool.
An earlier version allocated a new slice or map for the length which the decoder of its type decoded last: a small value kept the capacity which another call needed, and every goroutine wrote the length into the decoder they shared ( #775 ).
Others
I have done a lot of other optimizations. I will find time to write about them. If you have any questions about what's written here or other optimizations, please visit the #go-json channel on gophers.slack.com .
Reference
Regarding the story of go-json, there are the following articles in Japanese only.
- https://speakerdeck.com/goccy/zui-su-falsejsonraiburariwoqiu-mete
- https://engineering.mercari.com/blog/entry/1599563768-081104c850/
Looking for Sponsors
I'm looking for sponsors this library. This library is being developed as a personal project in my spare time. If you want a quick response or problem resolution when using this library in your project, please register as a sponsor. I will cooperate as much as possible. Of course, this library is developed as an MIT license, so you can use it freely for free.
License
MIT
 Documentation

Index 
- Variables
- func Compact(dst *bytes.Buffer, src []byte) error
- func HTMLEscape(dst *bytes.Buffer, src []byte)
- func Indent(dst *bytes.Buffer, src []byte, prefix, indent string) error
- func Marshal(v any) ([]byte, error)
- func MarshalContext(ctx context.Context, v any, optFuncs ...EncodeOptionFunc) ([]byte, error)
- func MarshalIndent(v any, prefix, indent string) ([]byte, error)
- func MarshalIndentWithOption(v any, prefix, indent string, optFuncs ...EncodeOptionFunc) ([]byte, error)
- func MarshalNoEscape(v any) ([]byte, error)deprecated
- func MarshalOf[T any](v T, optFuncs ...EncodeOptionFunc) ([]byte, error)
- func MarshalWithOption(v any, optFuncs ...EncodeOptionFunc) ([]byte, error)
- func Unmarshal(data []byte, v any) error
- func UnmarshalContext(ctx context.Context, data []byte, v any, optFuncs ...DecodeOptionFunc) error
- func UnmarshalNoEscape(data []byte, v any, optFuncs ...DecodeOptionFunc) errordeprecated
- func UnmarshalOf[T any](data []byte, v *T, optFuncs ...DecodeOptionFunc) error
- func UnmarshalWithOption(data []byte, v any, optFuncs ...DecodeOptionFunc) error
- func Valid(data []byte) bool
- type ColorFormat
- type ColorScheme
- type DecodeOption
- type DecodeOptionFunc
- type Decoder
- func (d *Decoder) Buffered() io.Reader
- func (d *Decoder) Decode(v any) error
- func (d *Decoder) DecodeContext(ctx context.Context, v any) error
- func (d *Decoder) DecodeWithOption(v any, optFuncs ...DecodeOptionFunc) error
- func (d *Decoder) DisallowUnknownFields()
- func (d *Decoder) InputOffset() int64
- func (d *Decoder) More() bool
- func (d *Decoder) Token() (Token, error)
- func (d *Decoder) UseNumber()
- type Delim
- type EncodeOption
- type EncodeOptionFunc
- func Colorize(scheme *ColorScheme) EncodeOptionFunc
- func Debug() EncodeOptionFunc
- func DebugDOT(w io.WriteCloser) EncodeOptionFunc
- func DebugWith(w io.Writer) EncodeOptionFunc
- func DisableHTMLEscape() EncodeOptionFunc
- func DisableNormalizeUTF8() EncodeOptionFunc
- func OptimizeFieldOrder() EncodeOptionFunc
- func UnorderedMap() EncodeOptionFunc
- type Encoder
- func (e *Encoder) Encode(v any) error
- func (e *Encoder) EncodeContext(ctx context.Context, v any, optFuncs ...EncodeOptionFunc) error
- func (e *Encoder) EncodeWithOption(v any, optFuncs ...EncodeOptionFunc) error
- func (e *Encoder) SetEscapeHTML(on bool)
- func (e *Encoder) SetIndent(prefix, indent string)
- type FieldQuery
- type FieldQueryString
- type InvalidUTF8Errordeprecated
- type InvalidUnmarshalError
- type Marshaler
- type MarshalerContext
- type MarshalerError
- type Number
- type Options
- func CallMethodsWithLegacySemantics(v bool) Options
- func DefaultOptionsV1() Options
- func FormatByteArrayAsArray(v bool) Options
- func FormatBytesWithLegacySemantics(v bool) Options
- func FormatDurationAsNano(v bool) Options
- func MatchCaseSensitiveDelimiter(v bool) Options
- func MergeWithLegacySemantics(v bool) Options
- func OmitEmptyWithLegacySemantics(v bool) Options
- func ParseBytesWithLooseRFC4648(v bool) Options
- func ParseTimeWithLooseRFC3339(v bool) Options
- func ReportErrorsWithLegacySemantics(v bool) Options
- func StringifyWithLegacySemantics(v bool) Options
- func UnmarshalArrayFromAnyLength(v bool) Options
- type Path
- func (p *Path) Extract(data []byte, optFuncs ...DecodeOptionFunc) ([][]byte, error)
- func (p *Path) Get(src, dst any) error
- func (p *Path) PathString() string
- func (p *Path) RootSelectorOnly() bool
- func (p *Path) Unmarshal(data []byte, v any, optFuncs ...DecodeOptionFunc) error
- func (p *Path) UsedDoubleQuotePathSelector() bool
- func (p *Path) UsedSingleQuotePathSelector() bool
- type PathError
- type RawMessage
- type SubFieldQuery
- type SyntaxError
- type Token
- type UnmarshalFieldErrordeprecated
- type UnmarshalTypeError
- type Unmarshaler
- type UnmarshalerContext
- type UnsupportedTypeError
- type UnsupportedValueError
Constants 
This section is empty.
Variables 
var (
	// FieldQueryFromContext get current FieldQuery from context.Context.
	FieldQueryFromContext = encoder.FieldQueryFromContext
	// SetFieldQueryToContext set current FieldQuery to context.Context.
	SetFieldQueryToContext = encoder.SetFieldQueryToContext
)
var (
	DefaultColorScheme = &ColorScheme{
		Int:       createColorFormat(fgHiMagentaColor),
		Uint:      createColorFormat(fgHiMagentaColor),
		Float:     createColorFormat(fgHiMagentaColor),
		Bool:      createColorFormat(fgHiYellowColor),
		String:    createColorFormat(fgHiGreenColor),
		Binary:    createColorFormat(fgHiRedColor),
		ObjectKey: createColorFormat(fgHiCyanColor),
		Null:      createColorFormat(fgBlueColor),
	}
)
Functions 
func Compact ¶ added in v0.1.3
Compact appends to dst the JSON-encoded src with insignificant space characters elided.
func HTMLEscape ¶ added in v0.1.3
HTMLEscape appends to dst the JSON-encoded src with <, >, &, U+2028 and U+2029 characters inside string literals changed to \u003c, \u003e, \u0026, \u2028, \u2029 so that the JSON will be safe to embed inside HTML <script> tags. For historical reasons, web browsers don't honor standard HTML escaping within <script> tags, so an alternative JSON encoding must be used.
func Indent ¶ added in v0.1.3
Indent appends to dst an indented form of the JSON-encoded src. Each element in a JSON object or array begins on a new, indented line beginning with prefix followed by one or more copies of indent according to the indentation nesting. The data appended to dst does not begin with the prefix nor any indentation, to make it easier to embed inside other formatted JSON data. Although leading space characters (space, tab, carriage return, newline) at the beginning of src are dropped, trailing space characters at the end of src are preserved and copied to dst. For example, if src has no trailing spaces, neither will dst; if src ends in a trailing newline, so will dst.
func Marshal 
Marshal returns the JSON encoding of v.
Marshal traverses the value v recursively. If an encountered value implements the Marshaler interface and is not a nil pointer, Marshal calls its MarshalJSON method to produce JSON. If no MarshalJSON method is present but the value implements encoding.TextMarshaler instead, Marshal calls its MarshalText method and encodes the result as a JSON string. The nil pointer exception is not strictly necessary but mimics a similar, necessary exception in the behavior of UnmarshalJSON.
Otherwise, Marshal uses the following type-dependent default encodings:
Boolean values encode as JSON booleans.
Floating point, integer, and Number values encode as JSON numbers.
String values encode as JSON strings coerced to valid UTF-8, replacing invalid bytes with the Unicode replacement rune. The angle brackets "<" and ">" are escaped to "\u003c" and "\u003e" to keep some browsers from misinterpreting JSON output as HTML. Ampersand "&" is also escaped to "\u0026" for the same reason. This escaping can be disabled using an Encoder that had SetEscapeHTML(false) called on it.
Array and slice values encode as JSON arrays, except that []byte encodes as a base64-encoded string, and a nil slice encodes as the null JSON value.
Struct values encode as JSON objects. Each exported struct field becomes a member of the object, using the field name as the object key, unless the field is omitted for one of the reasons given below.
The encoding of each struct field can be customized by the format string stored under the "json" key in the struct field's tag. The format string gives the name of the field, possibly followed by a comma-separated list of options. The name may be empty in order to specify options without overriding the default field name.
The "omitempty" option specifies that the field should be omitted from the encoding if the field has an empty value, defined as false, 0, a nil pointer, a nil interface value, and any empty array, slice, map, or string.
As a special case, if the field tag is "-", the field is always omitted. Note that a field with name "-" can still be generated using the tag "-,".
Examples of struct field tags and their meanings:
// Field appears in JSON as key "myName".
Field int `json:"myName"`

// Field appears in JSON as key "myName" and
// the field is omitted from the object if its value is empty,
// as defined above.
Field int `json:"myName,omitempty"`

// Field appears in JSON as key "Field" (the default), but
// the field is skipped if empty.
// Note the leading comma.
Field int `json:",omitempty"`

// Field is ignored by this package.
Field int `json:"-"`

// Field appears in JSON as key "-".
Field int `json:"-,"`
The "string" option signals that a field is stored as JSON inside a JSON-encoded string. It applies only to fields of string, floating point, integer, or boolean types. This extra level of encoding is sometimes used when communicating with JavaScript programs:
Int64String int64 `json:",string"`
The key name will be used if it's a non-empty string consisting of only Unicode letters, digits, and ASCII punctuation except quotation marks, backslash, and comma.
Anonymous struct fields are usually marshaled as if their inner exported fields were fields in the outer struct, subject to the usual Go visibility rules amended as described in the next paragraph. An anonymous struct field with a name given in its JSON tag is treated as having that name, rather than being anonymous. An anonymous struct field of interface type is treated the same as having that type as its name, rather than being anonymous.
The Go visibility rules for struct fields are amended for JSON when deciding which field to marshal or unmarshal. If there are multiple fields at the same level, and that level is the least nested (and would therefore be the nesting level selected by the usual Go rules), the following extra rules apply:
1) Of those fields, if any are JSON-tagged, only tagged fields are considered, even if there are multiple untagged fields that would otherwise conflict.
2) If there is exactly one field (tagged or not according to the first rule), that is selected.
3) Otherwise there are multiple fields, and all are ignored; no error occurs.
Handling of anonymous struct fields is new in Go 1.1. Prior to Go 1.1, anonymous struct fields were ignored. To force ignoring of an anonymous struct field in both current and earlier versions, give the field a JSON tag of "-".
Map values encode as JSON objects. The map's key type must either be a string, an integer type, or implement encoding.TextMarshaler. The map keys are sorted and used as JSON object keys by applying the following rules, subject to the UTF-8 coercion described for string values above:
- string keys are used directly
- encoding.TextMarshalers are marshaled
- integer keys are converted to strings
Pointer values encode as the value pointed to. A nil pointer encodes as the null JSON value.
Interface values encode as the value contained in the interface. A nil interface value encodes as the null JSON value.
Channel, complex, and function values cannot be encoded in JSON. Attempting to encode such a value causes Marshal to return an UnsupportedTypeError.
JSON cannot represent cyclic data structures and Marshal does not handle them. Passing cyclic structures to Marshal will result in an infinite recursion.
func MarshalContext ¶ added in v0.7.0
MarshalContext returns the JSON encoding of v with context.Context and EncodeOption.
func MarshalIndent 
MarshalIndent is like Marshal but applies Indent to format the output. Each JSON element in the output will begin on a new line beginning with prefix followed by one or more copies of indent according to the indentation nesting.
func MarshalIndentWithOption ¶ added in v0.1.12
func MarshalIndentWithOption(v any, prefix, indent string, optFuncs ...EncodeOptionFunc) ([]byte, error)
MarshalIndentWithOption is like Marshal but applies Indent to format the output with EncodeOption.
func MarshalNoEscape
deprecated
added in
v0.2.0
MarshalNoEscape returns the JSON encoding of v.
Deprecated: Use Marshal. MarshalNoEscape used to keep v from escaping to the heap, but the encoder refers to v by its address, which is not updated when the stack of the goroutine is copied while v is being encoded. A value left on the stack was then read from the freed stack, so MarshalNoEscape is now the same as Marshal.
func MarshalOf ¶ added in v0.11.0
func MarshalOf[T any](v T, optFuncs ...EncodeOptionFunc) ([]byte, error)
MarshalOf returns the JSON encoding of v, as Marshal does.
Marshal takes its argument as an interface value, so a value which is not a pointer is copied to the heap for every call. MarshalOf takes the value by its type, and it copies the value to a value in the heap which is reused, so it encodes a value without an allocation other than the one of the result.
Which one to use depends on what is passed:
- A value which is not a pointer ( a struct, an int, a string, ... ): MarshalOf(v) is faster than Marshal(v), because it saves the allocation. It also lets v stay on the stack of the caller, which Marshal(&v) doesn't.
- A pointer or a map: they are the same, because such a value is stored in an interface value without an allocation.
- A large value which is already referred to by a pointer p: Marshal(p) is the fastest. MarshalOf(*p) copies the whole value, which costs more as the value gets larger.
func MarshalWithOption ¶ added in v0.1.12
func MarshalWithOption(v any, optFuncs ...EncodeOptionFunc) ([]byte, error)
MarshalWithOption returns the JSON encoding of v with EncodeOption.
func Unmarshal 
Unmarshal parses the JSON-encoded data and stores the result in the value pointed to by v. If v is nil or not a pointer, Unmarshal returns an InvalidUnmarshalError.
Unmarshal uses the inverse of the encodings that Marshal uses, allocating maps, slices, and pointers as necessary, with the following additional rules:
To unmarshal JSON into a pointer, Unmarshal first handles the case of the JSON being the JSON literal null. In that case, Unmarshal sets the pointer to nil. Otherwise, Unmarshal unmarshals the JSON into the value pointed at by the pointer. If the pointer is nil, Unmarshal allocates a new value for it to point to.
To unmarshal JSON into a value implementing the Unmarshaler interface, Unmarshal calls that value's UnmarshalJSON method, including when the input is a JSON null. Otherwise, if the value implements encoding.TextUnmarshaler and the input is a JSON quoted string, Unmarshal calls that value's UnmarshalText method with the unquoted form of the string.
To unmarshal JSON into a struct, Unmarshal matches incoming object keys to the keys used by Marshal (either the struct field name or its tag), preferring an exact match but also accepting a case-insensitive match. By default, object keys which don't have a corresponding struct field are ignored (see Decoder.DisallowUnknownFields for an alternative).
To unmarshal JSON into an interface value, Unmarshal stores one of these in the interface value:
bool, for JSON booleans
float64, for JSON numbers
string, for JSON strings
[]interface{}, for JSON arrays
map[string]interface{}, for JSON objects
nil for JSON null
To unmarshal a JSON array into a slice, Unmarshal resets the slice length to zero and then appends each element to the slice. As a special case, to unmarshal an empty JSON array into a slice, Unmarshal replaces the slice with a new empty slice.
To unmarshal a JSON array into a Go array, Unmarshal decodes JSON array elements into corresponding Go array elements. If the Go array is smaller than the JSON array, the additional JSON array elements are discarded. If the JSON array is smaller than the Go array, the additional Go array elements are set to zero values.
To unmarshal a JSON object into a map, Unmarshal first establishes a map to use. If the map is nil, Unmarshal allocates a new map. Otherwise Unmarshal reuses the existing map, keeping existing entries. Unmarshal then stores key-value pairs from the JSON object into the map. The map's key type must either be any string type, an integer, implement json.Unmarshaler, or implement encoding.TextUnmarshaler.
If a JSON value is not appropriate for a given target type, or if a JSON number overflows the target type, Unmarshal skips that field and completes the unmarshaling as best it can. If no more serious errors are encountered, Unmarshal returns an UnmarshalTypeError describing the earliest such error. In any case, it's not guaranteed that all the remaining fields following the problematic one will be unmarshaled into the target object.
The JSON null value unmarshals into an interface, map, pointer, or slice by setting that Go value to nil. Because null is often used in JSON to mean “not present,” unmarshaling a JSON null into any other Go type has no effect on the value and produces no error.
When unmarshaling quoted strings, invalid UTF-8 or invalid UTF-16 surrogate pairs are not treated as an error. Instead, they are replaced by the Unicode replacement character U+FFFD.
func UnmarshalContext ¶ added in v0.7.0
UnmarshalContext parses the JSON-encoded data and stores the result in the value pointed to by v. If you implement the UnmarshalerContext interface, call it with ctx as an argument.
func UnmarshalNoEscape
deprecated
func UnmarshalNoEscape(data []byte, v any, optFuncs ...DecodeOptionFunc) error
UnmarshalNoEscape parses the JSON-encoded data and stores the result in the value pointed to by v.
Deprecated: Use UnmarshalOf, which lets the value stay on the stack of the caller. UnmarshalNoEscape used to keep v from escaping to the heap, but the decoder refers to v by its address, which is not updated when the stack of the goroutine is copied while v is being decoded, so UnmarshalNoEscape is now the same as UnmarshalWithOption.
func UnmarshalOf ¶ added in v0.11.0
func UnmarshalOf[T any](data []byte, v *T, optFuncs ...DecodeOptionFunc) error
UnmarshalOf parses the JSON-encoded data and stores the result in the value pointed to by v, as Unmarshal does.
Unmarshal takes its argument as an interface value, and the decoder refers to the value by its address, so the value always escapes to the heap. UnmarshalOf takes the pointer by its type and never gives it to the decoder: it copies *v to a value in the heap which is reused, decodes into that value, and copies the result back to *v. So v may point to a variable on the stack of the caller, and a value which needs no allocation of its own ( no pointer, slice, map or string to fill ) is decoded without an allocation. With DecodeNoCopyString, a string without an escape refers to data, and needs none either.
A value is copied twice, so a large value is faster with Unmarshal when it is in the heap anyway. As the result is a copy, an UnmarshalJSON or UnmarshalText method of a type in the value must not keep the address of its receiver, which is the address of the copy.
func UnmarshalWithOption ¶ added in v0.7.0
func UnmarshalWithOption(data []byte, v any, optFuncs ...DecodeOptionFunc) error
Types 
type ColorFormat ¶ added in v0.6.0
type ColorFormat = encoder.ColorFormat
type ColorScheme ¶ added in v0.6.0
type ColorScheme = encoder.ColorScheme
type DecodeOption ¶ added in v0.7.0
type DecodeOptionFunc ¶ added in v0.7.0
type DecodeOptionFunc func(*DecodeOption)
func DecodeFieldPriorityFirstWin ¶ added in v0.7.0
func DecodeFieldPriorityFirstWin() DecodeOptionFunc
DecodeFieldPriorityFirstWin in the default behavior, go-json, like encoding/json, will reflect the result of the last evaluation when a field with the same name exists. This option allow you to change this behavior. this option reflects the result of the first evaluation if a field with the same name exists. This behavior has a performance advantage as it allows the subsequent strings to be skipped if all fields have been evaluated.
func DecodeNoCopyString ¶ added in v0.11.0
func DecodeNoCopyString() DecodeOptionFunc
DecodeNoCopyString makes the decoded strings refer to the input instead of copies of their bytes, as sonic does by default: a string which has no escape is not copied. Then the input must not be modified while the decoded strings are used, and a decoded string keeps the input alive: the data given to Unmarshal, whole, or, with a Decoder, which has the bytes of its reader in its buffer only, the buffer which the value was read into, which the Decoder doesn't reuse then. A program which keeps a few values out of many inputs keeps all of those inputs alive so.
By default, a decoded string is a copy, as with encoding/json: the input may be modified or reused after the call, and a decoded string keeps alive no memory but its own.
type Decoder 
type Decoder struct {
	// contains filtered or unexported fields
}
func NewDecoder 
NewDecoder returns a new decoder that reads from r.
The decoder introduces its own buffering and may read data from r beyond the JSON values requested.
func (*Decoder) Buffered 
Buffered returns a reader of the data remaining in the Decoder's buffer. The reader is valid until the next call to Decode.
func (*Decoder) Decode 
Decode reads the next JSON-encoded value from its input and stores it in the value pointed to by v.
See the documentation for Unmarshal for details about the conversion of JSON into a Go value.
func (*Decoder) DecodeContext ¶ added in v0.7.0
DecodeContext reads the next JSON-encoded value from its input and stores it in the value pointed to by v with context.Context.
func (*Decoder) DecodeWithOption ¶ added in v0.7.0
func (d *Decoder) DecodeWithOption(v any, optFuncs ...DecodeOptionFunc) error
func (*Decoder) DisallowUnknownFields 
func (d *Decoder) DisallowUnknownFields()
DisallowUnknownFields causes the Decoder to return an error when the destination is a struct and the input contains object keys which do not match any non-ignored, exported fields in the destination.
func (*Decoder) InputOffset 
type EncodeOption ¶ added in v0.1.12
type EncodeOptionFunc ¶ added in v0.4.0
type EncodeOptionFunc func(*EncodeOption)
func Colorize ¶ added in v0.6.0
func Colorize(scheme *ColorScheme) EncodeOptionFunc
Colorize add an identifier for coloring to the string of the encoded result.
func Debug ¶ added in v0.4.9
func Debug() EncodeOptionFunc
Debug outputs debug information when panic occurs during encoding.
func DebugDOT ¶ added in v0.10.2
func DebugDOT(w io.WriteCloser) EncodeOptionFunc
DebugDOT sets the destination to write opcodes graph.
func DebugWith ¶ added in v0.9.7
func DebugWith(w io.Writer) EncodeOptionFunc
DebugWith sets the destination to write debug messages.
func DisableHTMLEscape ¶ added in v0.9.0
func DisableHTMLEscape() EncodeOptionFunc
DisableHTMLEscape disables escaping of HTML characters ( '&', '<', '>' ) when encoding string.
func DisableNormalizeUTF8 ¶ added in v0.9.0
func DisableNormalizeUTF8() EncodeOptionFunc
DisableNormalizeUTF8 By default, when encoding string, UTF8 characters in the range of 0x80 - 0xFF are processed by replacing invalid code with U+FFFD and escaping \u2028 and \u2029, as encoding/json does: the replacement character is written escaped as \ufffd before Go 1.27, and as it is by Go 1.27, whose encoding/json is made of encoding/json/v2. This option disables this behaviour. You can expect faster speeds by applying this option, but be careful. encoding/json implements here: https://github.com/golang/go/blob/6178d25fc0b28724b1b5aec2b1b74fc06d9294c7/src/encoding/json/encode.go#L1067-L1093.
func OptimizeFieldOrder ¶ added in v0.11.0
func OptimizeFieldOrder() EncodeOptionFunc
OptimizeFieldOrder lets the encoder order the fields of a struct as it encodes them fastest, instead of in the order of the struct as encoding/json does: the fields of the same kind ( int, uint, float64, string, bool ) are put together, in the order of the first field of each kind, and are encoded without a dispatch between them; and a field of the struct's own type, if there is one, is put last, so that a list of values is encoded without a frame for each. The keys of the JSON object are the same, only their order differs, which a JSON object doesn't define.
func UnorderedMap ¶ added in v0.1.12
func UnorderedMap() EncodeOptionFunc
UnorderedMap doesn't sort when encoding map type: the entries of a map are written in an order which is not specified, and which may differ from the order of a range over the map.
type Encoder 
type Encoder struct {
	// contains filtered or unexported fields
}
An Encoder writes JSON values to an output stream.
func NewEncoder 
NewEncoder returns a new encoder that writes to w.
func (*Encoder) Encode 
Encode writes the JSON encoding of v to the stream, followed by a newline character.
See the documentation for Marshal for details about the conversion of Go values to JSON.
func (*Encoder) EncodeContext ¶ added in v0.7.0
EncodeContext call Encode with context.Context and EncodeOption.
func (*Encoder) EncodeWithOption ¶ added in v0.1.12
func (e *Encoder) EncodeWithOption(v any, optFuncs ...EncodeOptionFunc) error
EncodeWithOption call Encode with EncodeOption.
func (*Encoder) SetEscapeHTML 
SetEscapeHTML specifies whether problematic HTML characters should be escaped inside JSON quoted strings. The default behavior is to escape &, <, and > to \u0026, \u003c, and \u003e to avoid certain safety problems that can arise when embedding JSON in HTML.
In non-HTML settings where the escaping interferes with the readability of the output, SetEscapeHTML(false) disables this behavior.
type FieldQuery ¶ added in v0.9.0
type FieldQuery = encoder.FieldQuery
FieldQuery you can dynamically filter the fields in the structure by creating a FieldQuery, adding it to context.Context using SetFieldQueryToContext and then passing it to MarshalContext. This is a type-safe operation, so it is faster than filtering using map[string]interface{}.
func BuildFieldQuery ¶ added in v0.9.0
func BuildFieldQuery(fields ...FieldQueryString) (*FieldQuery, error)
BuildFieldQuery builds FieldQuery by fieldName or sub field query. First, specify the field name that you want to keep in structure type. If the field you want to keep is a structure type, by creating a sub field query using BuildSubFieldQuery, you can select the fields you want to keep in the structure. This description can be written recursively.
type FieldQueryString ¶ added in v0.9.0
type FieldQueryString = encoder.FieldQueryString
type InvalidUTF8Error
deprecated
type InvalidUTF8Error = errors.InvalidUTF8Error
Before Go 1.2, an InvalidUTF8Error was returned by Marshal when attempting to encode a string value with invalid UTF-8 sequences. As of Go 1.2, Marshal instead coerces the string to valid UTF-8 by replacing invalid bytes with the Unicode replacement rune U+FFFD.
Deprecated: No longer used; kept for compatibility.
type InvalidUnmarshalError 
type InvalidUnmarshalError = errors.InvalidUnmarshalError
An InvalidUnmarshalError describes an invalid argument passed to Unmarshal. (The argument to Unmarshal must be a non-nil pointer.)
type Marshaler 
Marshaler is the interface implemented by types that can marshal themselves into valid JSON.
type MarshalerContext ¶ added in v0.7.0
MarshalerContext is the interface implemented by types that can marshal themselves into valid JSON with context.Context.
type MarshalerError 
type MarshalerError = errors.MarshalerError
A MarshalerError represents an error from calling a MarshalJSON or MarshalText method.
type Options ¶ added in v0.12.0
Options are the options of github.com/goccy/go-json/v2 and github.com/goccy/go-json/jsontext, which DefaultOptionsV1 and the options of the semantics of this package below, the ones of encoding/json, such as FormatDurationAsNano, make, as encoding/json makes them for encoding/json/v2: each of them makes one behavior of the v2 semantics the one of this package, alone or with the others, and DefaultOptionsV1 makes them all the ones of this package. They are not EncodeOptionFunc and DecodeOptionFunc, which are the options of the functions of this package. It is the same type as the Options of those packages.
jsonv2.Marshal(v, json.DefaultOptionsV1())         // as json.Marshal(v)
jsonv2.Unmarshal(b, &v, json.FormatDurationAsNano(true))
func CallMethodsWithLegacySemantics ¶ added in v0.12.0
CallMethodsWithLegacySemantics specifies that the methods of marshaling and unmarshaling are called as this package calls them:
- When marshaling, a method of a pointer receiver is called only for a value which is addressable: a value which a pointer points to, an element of a slice, and a field of a struct or an element of an array which is addressable. A value held by an interface, a key or a value of a map, and a value given by itself are not.
- A key of a map is not marshaled or unmarshaled by MarshalJSON, MarshalJSONTo, UnmarshalJSON or UnmarshalJSONFrom, but still by MarshalText, AppendText and UnmarshalText, of which a key of a string kind calls none when marshaling.
- When marshaling, a key of a map which is a nil pointer with MarshalText or AppendText is the name "".
- When marshaling, a value of an interface type with a method of marshaling which holds a nil pointer is marshaled by the method, not as null.
This affects marshaling and unmarshaling. It is true by default in this package.
func DefaultOptionsV1 ¶ added in v0.12.0
func DefaultOptionsV1() Options
DefaultOptionsV1 sets every option whose default differs between this package and github.com/goccy/go-json/v2 to the default of this package: AllowDuplicateNames, AllowInvalidUTF8, EscapeForHTML, EscapeForJS and PreserveRawStrings of jsontext, Deterministic, FormatNilMapAsNull, FormatNilSliceAsNull and MatchCaseInsensitiveNames of github.com/goccy/go-json/v2, and CallMethodsWithLegacySemantics, FormatByteArrayAsArray, FormatBytesWithLegacySemantics, FormatDurationAsNano, MatchCaseSensitiveDelimiter, MergeWithLegacySemantics, OmitEmptyWithLegacySemantics, ParseBytesWithLooseRFC4648, ParseTimeWithLooseRFC3339, ReportErrorsWithLegacySemantics, StringifyWithLegacySemantics and UnmarshalArrayFromAnyLength of this package, all true. Other options are not set.
Marshal and Unmarshal of github.com/goccy/go-json/v2 with it marshal and unmarshal as Marshal and Unmarshal of encoding/json of Go 1.27 do.
func FormatByteArrayAsArray ¶ added in v0.12.0
FormatByteArrayAsArray specifies that a Go [N]byte is a JSON array of numbers, as any other array, rather than a JSON string of the base64 of its bytes.
This affects marshaling and unmarshaling. It is true by default in this package.
func FormatBytesWithLegacySemantics ¶ added in v0.12.0
FormatBytesWithLegacySemantics specifies that the slices and the arrays of bytes are handled as this package handles them:
- A slice or an array of a named type of bytes is a JSON string of the base64 of its bytes, as a []byte is, rather than a JSON array of its elements; but it is still a JSON array of its elements when marshaling if the type of the bytes has a method of marshaling, and an array is one with FormatByteArrayAsArray.
- When unmarshaling, a JSON array is read into a slice or an array of bytes element by element, as into any other slice or array, where it is an error by default.
This affects marshaling and unmarshaling. It is true by default in this package.
func FormatDurationAsNano ¶ added in v0.12.0
FormatDurationAsNano specifies that a time.Duration is a JSON number of its nanoseconds, rather than an error.
This affects marshaling and unmarshaling. It is true by default in this package.
func MatchCaseSensitiveDelimiter ¶ added in v0.12.0
MatchCaseSensitiveDelimiter specifies that the names which are matched case-insensitively, by MatchCaseInsensitiveNames of github.com/goccy/go-json/v2 or the case:ignore option of a field, are matched by strings.EqualFold: an underscore or a dash is not ignored.
This affects marshaling and unmarshaling. It is true by default in this package.
func MergeWithLegacySemantics ¶ added in v0.12.0
MergeWithLegacySemantics specifies that unmarshaling into a Go value which is not zero merges into it as this package does:
- A JSON null leaves a bool, a number, a string, an array, a struct and a value with UnmarshalText as they are, and sets any other value to zero.
- A JSON value other than null is read into the value which the element of an array or a slice, even past the length of the slice, a field of a struct, a pointer, or a non-nil pointer held by an interface has, rather than into a zero value; a value of a map is replaced. A slice is cut at the length of the JSON array.
This affects unmarshaling only. It is true by default in this package.
func OmitEmptyWithLegacySemantics ¶ added in v0.12.0
OmitEmptyWithLegacySemantics specifies that the omitempty option of a field omits it if its Go value is false, 0, a nil pointer, a nil interface value, or an empty array, slice, map or string, rather than if it is marshaled as a JSON null or an empty JSON string, array or object.
This affects marshaling only. It is true by default in this package.
func ParseBytesWithLooseRFC4648 ¶ added in v0.12.0
ParseBytesWithLooseRFC4648 specifies that the base64 of a JSON string read into bytes may have carriage returns and line feeds, which are skipped.
This affects unmarshaling only. It is true by default in this package.
func ParseTimeWithLooseRFC3339 ¶ added in v0.12.0
ParseTimeWithLooseRFC3339 specifies that a time.Time may be read from a JSON string which RFC 3339 doesn't allow in these ways: an hour of one digit, a comma before the fraction of a second, and a timezone offset whose hour is 24 or whose minute is 60.
This affects unmarshaling only. It is true by default in this package.
func ReportErrorsWithLegacySemantics ¶ added in v0.12.0
ReportErrorsWithLegacySemantics specifies that the errors are reported as this package reports them:
- The errors are usually of the types of this package, such as SyntaxError, MarshalerError, UnsupportedTypeError, UnsupportedValueError, InvalidUnmarshalError and UnmarshalTypeError, rather than SemanticError of github.com/goccy/go-json/v2 and SyntacticError of github.com/goccy/go-json/jsontext.
- The error of a method of marshaling is wrapped in a MarshalerError, and the one of a method of unmarshaling is returned as it is.
- A struct type with an error, such as two fields of the same name or a wrong tag, is handled as well as it can be, rather than as an error.
- A name which matches no field exactly and more than one field case-insensitively, by MatchCaseInsensitiveNames of github.com/goccy/go-json/v2 or the case:ignore option of a field, is read into the first of them, rather than being an error.
- The whole JSON value is checked before it is unmarshaled, so that an input with a syntax error changes nothing, and an error of a value doesn't stop the unmarshaling: the first such error is reported at the end.
This affects marshaling and unmarshaling. It is true by default in this package.
func StringifyWithLegacySemantics ¶ added in v0.12.0
StringifyWithLegacySemantics specifies that the string option of a field applies as in this package:
- It applies to a bool and a string too, and to a pointer to one, whose JSON value is in a JSON string.
- When unmarshaling, a number in a JSON string is read by the syntax of Go numbers, of which the JSON numbers are a part, and a JSON string of null is a JSON null.
If ReportErrorsWithLegacySemantics is false, the string option of a value which it doesn't apply to is an error, rather than ignored.
This affects marshaling and unmarshaling. It is true by default in this package.
func UnmarshalArrayFromAnyLength ¶ added in v0.12.0
UnmarshalArrayFromAnyLength specifies that a Go array is read from a JSON array of any length: the elements past the length of the Go array are skipped, and the ones which the JSON array doesn't have are zero, rather than an error.
This affects unmarshaling only. It is true by default in this package.
type Path ¶ added in v0.10.0
type Path struct {
	// contains filtered or unexported fields
}
Path represents JSON Path.
func CreatePath ¶ added in v0.10.0
CreatePath creates JSON Path.
JSON Path rule $ : root object or element. The JSON Path format must start with this operator, which refers to the outermost level of the JSON-formatted string. . : child operator. You can identify child values using dot-notation. .. : recursive descent. [] : subscript operator. If the JSON object is an array, you can use brackets to specify the array index. [*] : all objects/elements for array.
Reserved words must be properly escaped when included in Path.
Escape Rule single quote style escape: e.g.) `$['a.b'].c` double quote style escape: e.g.) `$."a.b".c`
func (*Path) Extract ¶ added in v0.10.0
func (p *Path) Extract(data []byte, optFuncs ...DecodeOptionFunc) ([][]byte, error)
Extract extracts a specific JSON string.
func (*Path) Get ¶ added in v0.10.0
Get extract and substitute the value of the part corresponding to JSON Path from the input value.
func (*Path) PathString ¶ added in v0.10.0
PathString returns original JSON Path string.
func (*Path) RootSelectorOnly ¶ added in v0.10.0
RootSelectorOnly whether only the root selector ($) is used.
func (*Path) Unmarshal ¶ added in v0.10.0
func (p *Path) Unmarshal(data []byte, v any, optFuncs ...DecodeOptionFunc) error
Unmarshal extract and decode the value of the part corresponding to JSON Path from the input data.
func (*Path) UsedDoubleQuotePathSelector ¶ added in v0.10.0
UsedDoubleQuotePathSelector whether double quote-based escaping was done when building the JSON Path.
func (*Path) UsedSingleQuotePathSelector ¶ added in v0.10.0
UsedSingleQuotePathSelector whether single quote-based escaping was done when building the JSON Path.
type RawMessage ¶ added in v0.1.3
type RawMessage = json.RawMessage
RawMessage is a raw encoded JSON value. It implements Marshaler and Unmarshaler and can be used to delay JSON decoding or precompute a JSON encoding.
type SubFieldQuery ¶ added in v0.9.0
type SubFieldQuery struct {
	// contains filtered or unexported fields
}
func BuildSubFieldQuery ¶ added in v0.9.0
func BuildSubFieldQuery(name string) *SubFieldQuery
BuildSubFieldQuery builds sub field query.
func (*SubFieldQuery) Fields ¶ added in v0.9.0
func (q *SubFieldQuery) Fields(fields ...FieldQueryString) FieldQueryString
type SyntaxError 
type SyntaxError = errors.SyntaxError
A SyntaxError is a description of a JSON syntax error.
type Token 
A Token holds a value of one of these types:
Delim, for the four JSON delimiters [ ] { }
bool, for JSON booleans
float64, for JSON numbers
Number, for JSON numbers
string, for JSON string literals
nil, for JSON null
type UnmarshalFieldError
deprecated
type UnmarshalFieldError = errors.UnmarshalFieldError
An UnmarshalFieldError describes a JSON object key that led to an unexported (and therefore unwritable) struct field.
Deprecated: No longer used; kept for compatibility.
type UnmarshalTypeError 
type UnmarshalTypeError = errors.UnmarshalTypeError
An UnmarshalTypeError describes a JSON value that was not appropriate for a value of a specific Go type.
type Unmarshaler 
Unmarshaler is the interface implemented by types that can unmarshal a JSON description of themselves. The input can be assumed to be a valid encoding of a JSON value. UnmarshalJSON must copy the JSON data if it wishes to retain the data after returning.
By convention, to approximate the behavior of Unmarshal itself, Unmarshalers implement UnmarshalJSON([]byte("null")) as a no-op.
type UnmarshalerContext ¶ added in v0.7.0
UnmarshalerContext is the interface implemented by types that can unmarshal with context.Context a JSON description of themselves.
type UnsupportedTypeError 
type UnsupportedTypeError = errors.UnsupportedTypeError
An UnsupportedTypeError is returned by Marshal when attempting to encode an unsupported value type.
type UnsupportedValueError 
type UnsupportedValueError = errors.UnsupportedValueError
 Source Files

 Directories

| Path | Synopsis |
|---|---|
|
internal
|
|
|
cmd/benchcheck
command
benchcheck detects performance degradation by comparing the benchmark results of the current working tree with those of the base branch.
|
benchcheck detects performance degradation by comparing the benchmark results of the current working tree with those of the base branch. |
|
cmd/float_table
command
float_table writes the table of the powers of ten of shortestDecimal ( internal/floatfmt/float_table.go ): for each k from floatKMin to floatKMax, g = ⌊10⁻ᵏ·2¹²⁵⁻ᶠ⌋ + 1, where f = ⌊−k·log₂10⌋ as floorLog2Pow10 computes it, so that 2¹²⁵ ≤ g < 2¹²⁶, as its high 63 bits and its low 63 bits.
|
float_table writes the table of the powers of ten of shortestDecimal ( internal/floatfmt/float_table.go ): for each k from floatKMin to floatKMax, g = ⌊10⁻ᵏ·2¹²⁵⁻ᶠ⌋ + 1, where f = ⌊−k·log₂10⌋ as floorLog2Pow10 computes it, so that 2¹²⁵ ≤ g < 2¹²⁶, as its high 63 bits and its low 63 bits. |
|
cmd/generator
command
|
|
|
cmd/pow10table
command
pow10table writes the table of the powers of ten which jsonnum.ParseFloat multiplies a mantissa by ( internal/jsonnum/pow10_table.go ).
|
pow10table writes the table of the powers of ten which jsonnum.ParseFloat multiplies a mantissa by ( internal/jsonnum/pow10_table.go ). |
|
encoder
This files's processing codes are inspired by https://github.com/segmentio/encoding.
|
This files's processing codes are inspired by https://github.com/segmentio/encoding. |
|
encoder/run
Package run drives the encoder: it compiles the opcodes of a value, sets up the runtime context and runs the VM which the options choose.
|
Package run drives the encoder: it compiles the opcodes of a value, sets up the runtime context and runs the VM which the options choose. |
|
encoder/vm
Code generated by internal/cmd/generator.
|
Code generated by internal/cmd/generator. |
|
encoder/vm_color
Code generated by internal/cmd/generator.
|
Code generated by internal/cmd/generator. |
|
encoder/vm_color_indent
Code generated by internal/cmd/generator.
|
Code generated by internal/cmd/generator. |
|
encoder/vm_indent
Code generated by internal/cmd/generator.
|
Code generated by internal/cmd/generator. |
|
floatfmt
Package floatfmt writes floats as JSON numbers, by their shortest decimal, as ECMA-262 formats numbers: the format of encoding/json and of encoding/json/jsontext.
|
Package floatfmt writes floats as JSON numbers, by their shortest decimal, as ECMA-262 formats numbers: the format of encoding/json and of encoding/json/jsontext. |
|
intfmt
This files's processing codes are inspired by https://github.com/segmentio/encoding.
|
This files's processing codes are inspired by https://github.com/segmentio/encoding. |
|
jsonfields
Package jsonfields finds the JSON object members of a Go struct by the rules of encoding/json/v2: the fields which a value of the struct is marshaled to and unmarshaled from, with the options of their `json` tags.
|
Package jsonfields finds the JSON object members of a Go struct by the rules of encoding/json/v2: the fields which a value of the struct is marshaled to and unmarshaled from, with the options of their `json` tags. |
|
jsonnum
Package jsonnum reads JSON numbers by the grammar of RFC 8259, section 6, for the encoder and the decoder of encoding/json and for jsontext.
|
Package jsonnum reads JSON numbers by the grammar of RFC 8259, section 6, for the encoder and the decoder of encoding/json and for jsontext. |
|
jsonstring
This files's string processing codes are inspired by https://github.com/segmentio/encoding.
|
This files's string processing codes are inspired by https://github.com/segmentio/encoding. |
|
jsonsyntax
Package jsonsyntax passes the syntax errors of the package jsontext to encoding/json, which reports them in its own words: jsontext keeps how an error is made, which encoding/json can't see from outside of it.
|
Package jsonsyntax passes the syntax errors of the package jsontext to encoding/json, which reports them in its own words: jsontext keeps how an error is made, which encoding/json can't see from outside of it. |
|
options
Package options is the state of the options of jsontext and of the v2 json package: both packages take the same Options, so that the options of one may be given to the functions of the other, as encoding/json/v2 and encoding/json/jsontext allow.
|
Package options is the state of the options of jsontext and of the v2 json package: both packages take the same Options, so that the options of one may be given to the functions of the other, as encoding/json/v2 and encoding/json/jsontext allow. |
|
textcoder
Package textcoder lets the v2 json package give a jsontext.Encoder to a method or a function of marshaling, which writes after the output of the encoder of the v2 semantics: jsontext sets these functions, which take its encoder as an any, since this package can't import jsontext.
|
Package textcoder lets the v2 json package give a jsontext.Encoder to a method or a function of marshaling, which writes after the output of the encoder of the v2 semantics: jsontext sets these functions, which take its encoder as an any, since this package can't import jsontext. |
|
Package jsontext reads and writes the syntax of JSON, as RFC 4627, RFC 7159, RFC 7493, RFC 8259 and RFC 8785 specify it.
|
Package jsontext reads and writes the syntax of JSON, as RFC 4627, RFC 7159, RFC 7493, RFC 8259 and RFC 8785 specify it. |
|
Package json converts Go values to JSON and back, with the API of encoding/json/v2 of Go 1.27: code which imports encoding/json/v2 can import github.com/goccy/go-json/v2 instead, and code which imports encoding/json/jsontext can import github.com/goccy/go-json/jsontext.
|
Package json converts Go values to JSON and back, with the API of encoding/json/v2 of Go 1.27: code which imports encoding/json/v2 can import github.com/goccy/go-json/v2 instead, and code which imports encoding/json/jsontext can import github.com/goccy/go-json/jsontext. |